Less than 1/10th the cost.
Over 8× faster decisions.
A 0.6B model on your own machine. Route requests locally and send the uncertain ones to Fable 5, Astra, or DeepSeek Pro.
Savings against each model alone · 500-case routing replay · Low reasoning effort
Local compute estimated at $0.50/hour, fully utilized · Accuracy trade-offs below
Versus Fable 5, Astra, and DeepSeek Pro alone
Replay using measured local and API durations
490 of 500 decisions handled locally in replay
SmallDecide runs on your own machine. In this 500-case routing replay, its confidence gate handled 490 requests locally and sent ten to an API. Accepted requests need no network call or per-token API charge; local compute is included in the cost estimate.
Putting it ahead of Fable 5, Astra, or DeepSeek Pro brought estimated cost below one tenth of using those APIs alone. Median decisions were over 8 times faster. These savings come from replaying a confidence-based gate over measured local and API responses.
One local model. 30 hosted APIs.
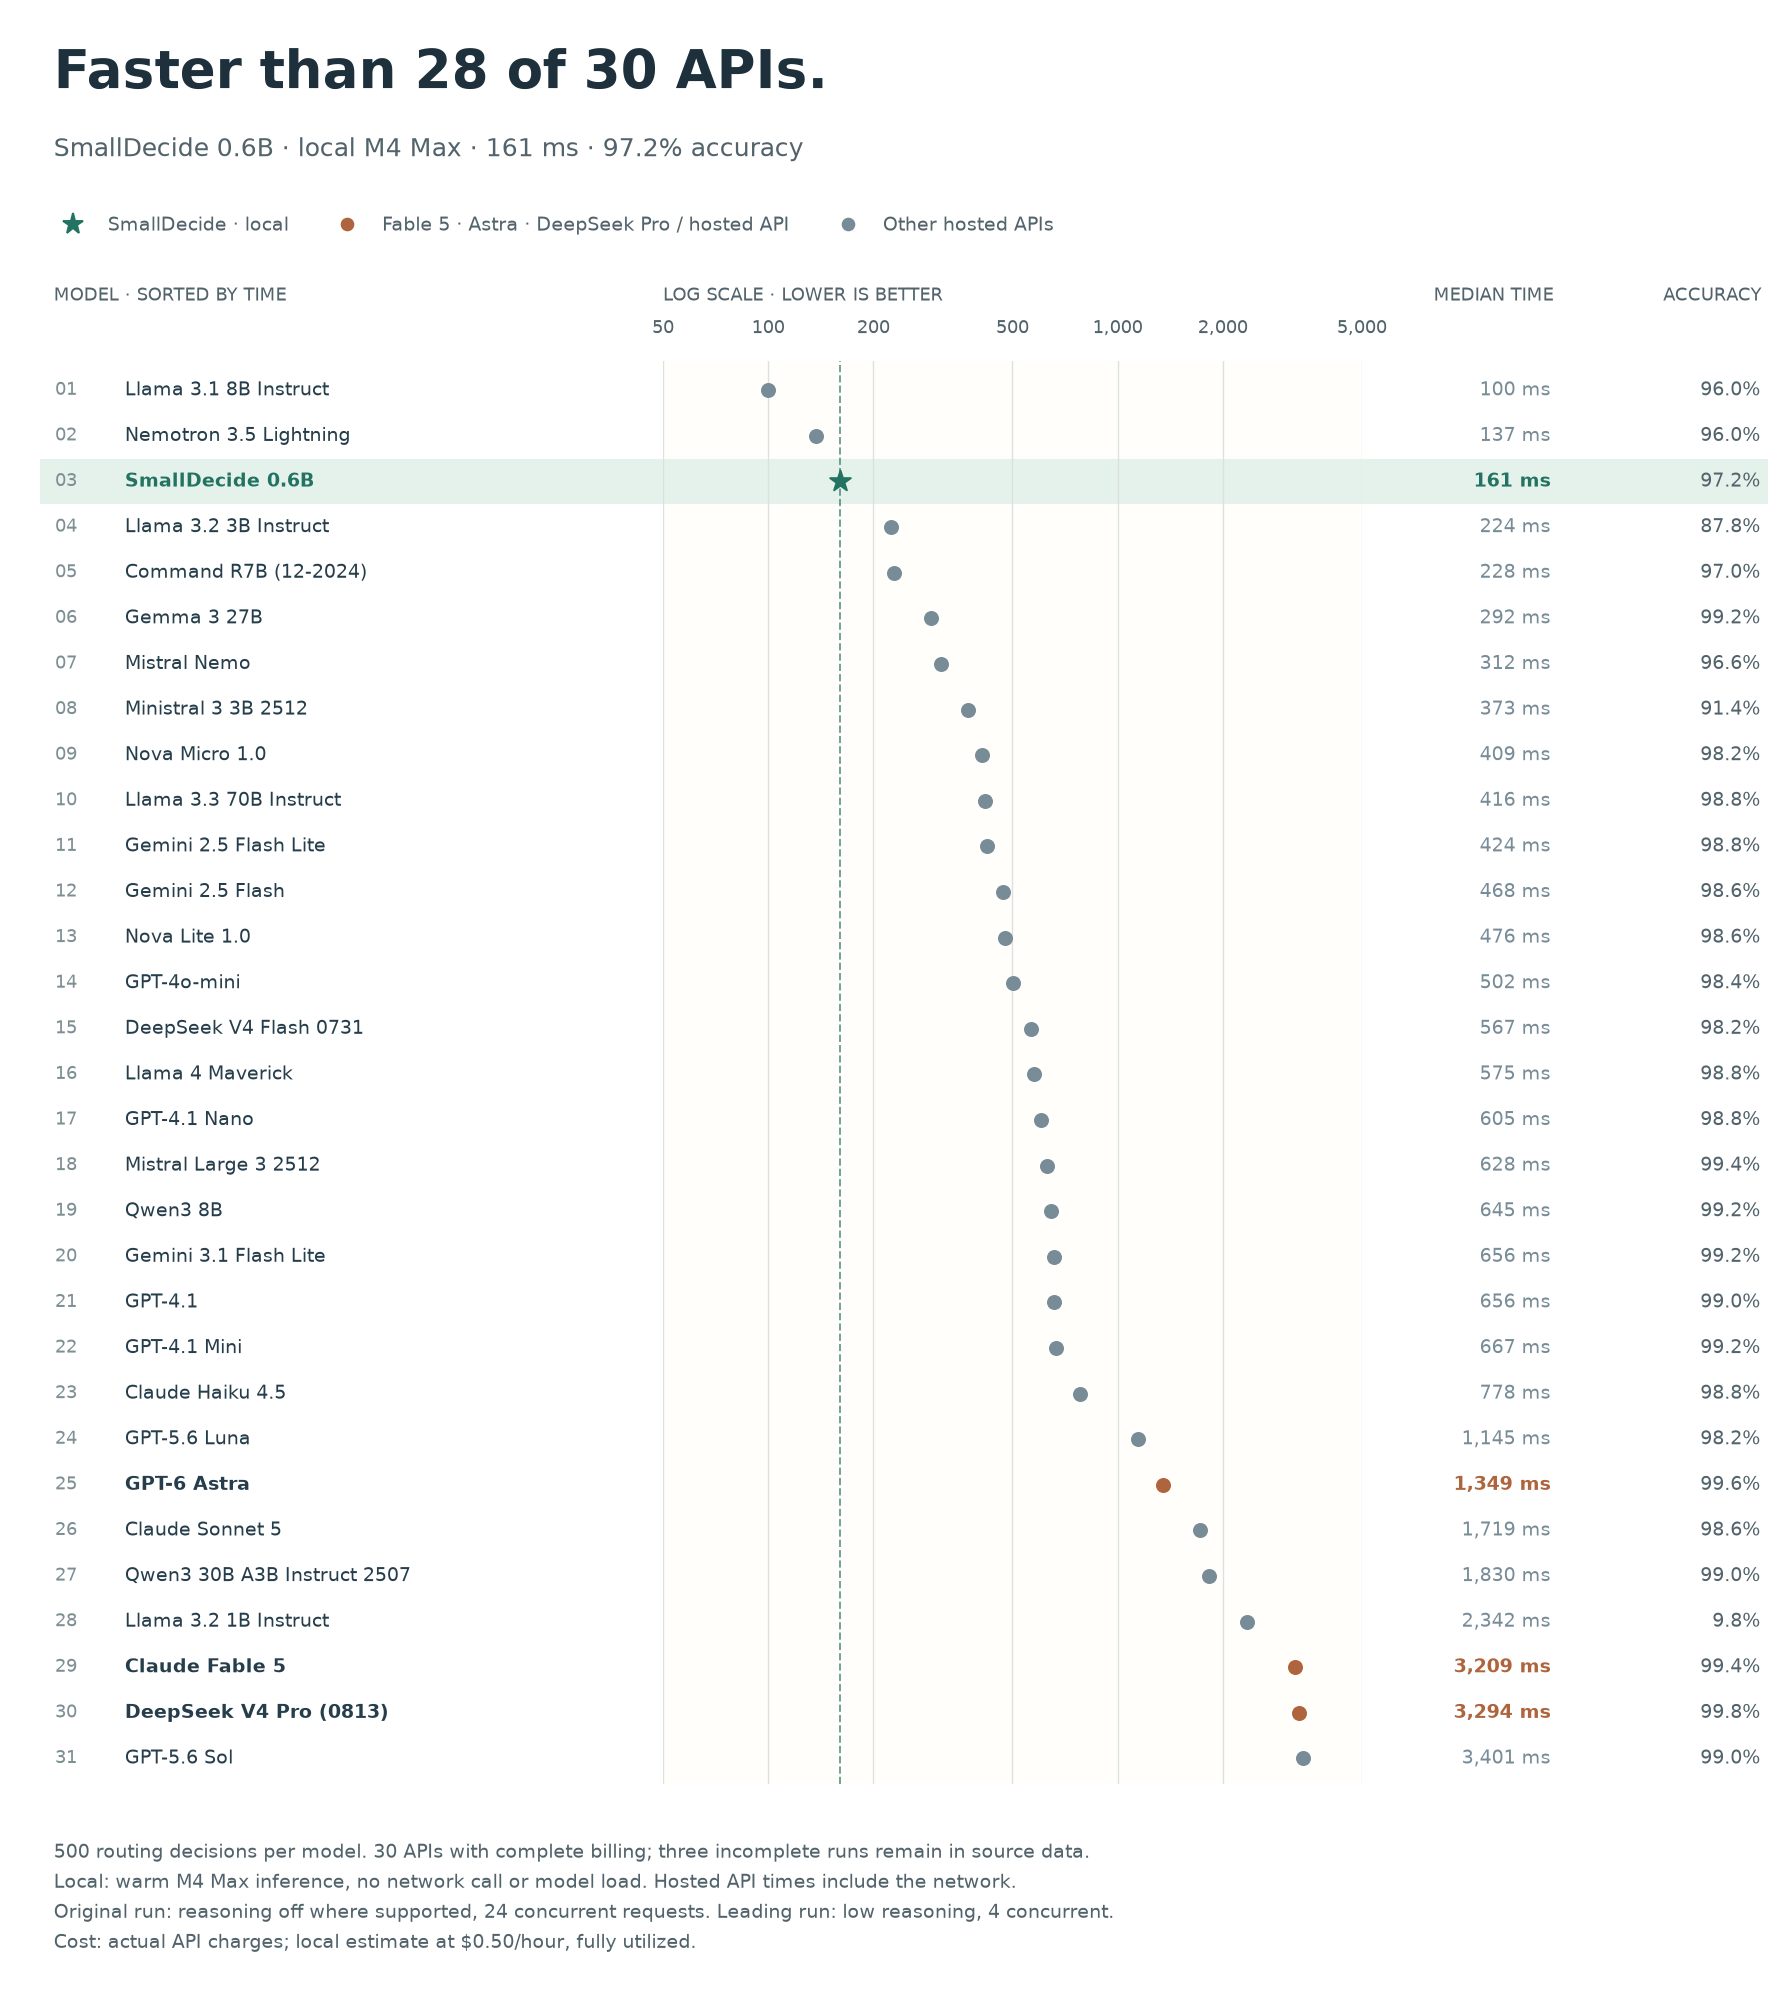
Faster than 28 of 30 APIs.
SmallDecide on an M4 Max.
A 0.6B model running on your own machine, with no network call. Median routing times against three leading hosted APIs:
97.2% accuracy · 500 routing decisions · Warm inference, model load excluded
- vs Claude Fable 5
- 20.0× faster locally
- vs GPT-6 Astra
- 8.4× faster locally
- vs DeepSeek V4 Pro (0813)
- 20.5× faster locally
3,209 ms via API · 99.4% accuracy
1,349 ms via API · 99.6% accuracy
3,294 ms via API · 99.8% accuracy
Every API with higher accuracy took longer.
Milliseconds · logarithmic scale · lower is better. Dashed line: SmallDecide’s median time.
30 APIs with complete billing records. Three incomplete runs are retained in the source data. SmallDecide scored 97.2%; the two faster APIs scored 96.0%. Local timings measure warm M4 Max compute; API timings include the network. The two runs used different reasoning settings and concurrency.
Fable 5 / Astra / DeepSeek V4 Pro
Cost and time with SmallDecide
Each API on its own, then with SmallDecide handling confident requests locally.
Claude Fable 5
96.8%lower estimated cost
- Cost / 1,000
- $1.9394 → $0.0617
- Median time
- 3,209 → 162 ms (19.8× faster)
- Accuracy
- 99.4% → 98.2%497 → 491 correct / 500
Direct API → with SmallDecide
GPT-6 Astra
96.5%lower estimated cost
- Cost / 1,000
- $1.5839 → $0.0548
- Median time
- 1,349 → 162 ms (8.3× faster)
- Accuracy
- 99.6% → 98.4%498 → 492 correct / 500
Direct API → with SmallDecide
DeepSeek V4 Pro (0813)
91.2%lower estimated cost
- Cost / 1,000
- $0.4478 → $0.0395
- Median time
- 3,294 → 162 ms (20.3× faster)
- Accuracy
- 99.8% → 98.4%499 → 492 correct / 500
Direct API → with SmallDecide
Same 500 frozen cases; low reasoning effort; actual API charges, including billed reasoning tokens. Local cost assumes $0.50/hour at full utilization. Exact comparisons ↓ · Intervals, p95, tokens + providers ↗
How the gate works
SmallDecide scores the candidate answers. If its maximum candidate probability is at least 0.8502035140991211, the local answer is accepted. This is distinct from the API’s entropy-based confidence field. Otherwise, the request goes to the selected API. We fixed that threshold using 200 separate validation cases before the original test.
The estimate charges for local compute on every request and API calls on escalations. Every test case was sent to every API to establish the baseline; the avoided calls are calculated from those stored responses.
With and without SmallDecide
96.5% lower estimated cost
API measurement → hybrid replay
Paired correctness changes are shown when JavaScript is enabled.
490 local decisions, 10 escalations. Eight accepted local answers were wrong: a 1.63% error rate, above the 1% validation target. Source replay results ↓
Accuracy trade-off
With Astra, the combined system scores 492/500, versus 498/500 for Astra alone. Estimated cost falls 96.5%; median decision time falls from 1,349 to 162 milliseconds.
The gate accepts some incorrect local answers with high confidence. A production threshold needs validation on the traffic it will handle.
Some small APIs cost less than local inference. Command R7B (12-2024) costs $0.00482 per 1,000 at 97.0% accuracy, compared with SmallDecide’s estimated $0.02307 at 97.2%. Adding the local gate to a cheap API can increase the bill.
Results
30 APIs and SmallDecide on the same 500 cases. API costs are recorded charges; local cost assumes $0.50/hour at full utilization. Accuracy includes failures. Intervals are 95% Wilson intervals.
| Model / execution | Accuracy / interval | Median | p95 | Cost / 1,000 | Errors* |
|---|---|---|---|---|---|
| Llama 3.1 8B InstructHosted API | 96.0%480/500 · 93.9%–97.4% | 100ms | 158ms | $0.03069 | 0 |
| Nemotron 3.5 LightningHosted API | 96.0%480/500 · 93.9%–97.4% | 137ms | 226ms | $0.01051 | 0 |
| SmallDecide 0.6BLocal · M4 Max · estimated cost | 97.2%486/500 · 95.4%–98.3% | 161ms | 222ms | $0.02307 | 0 |
| Llama 3.2 3B InstructHosted API | 87.8%439/500 · 84.6%–90.4% | 224ms | 391ms | $0.00877 | 0 |
| Command R7B (12-2024)Hosted API | 97.0%485/500 · 95.1%–98.2% | 228ms | 319ms | $0.00482 | 0 |
| Gemma 3 27BHosted API | 99.2%496/500 · 98.0%–99.7% | 292ms | 598ms | $0.01417 | 0 |
| Mistral NemoHosted API | 96.6%483/500 · 94.6%–97.9% | 312ms | 551ms | $0.00551 | 2 |
| Ministral 3 3B 2512Hosted API | 91.4%457/500 · 88.6%–93.6% | 373ms | 695ms | $0.01212 | 0 |
| Nova Micro 1.0Hosted API | 98.2%491/500 · 96.6%–99.1% | 409ms | 545ms | $0.00502 | 1 |
| Llama 3.3 70B InstructHosted API | 98.8%494/500 · 97.4%–99.4% | 416ms | 1669ms | $0.02972 | 0 |
| Gemini 2.5 Flash LiteHosted API | 98.8%494/500 · 97.4%–99.4% | 424ms | 558ms | $0.01301 | 0 |
| Gemini 2.5 FlashHosted API | 98.6%493/500 · 97.1%–99.3% | 468ms | 662ms | $0.04047 | 1 |
| Nova Lite 1.0Hosted API | 98.6%493/500 · 97.1%–99.3% | 476ms | 2969ms | $0.00860 | 0 |
| GPT-4o-miniHosted API | 98.4%492/500 · 96.9%–99.2% | 502ms | 685ms | $0.02048 | 2 |
| DeepSeek V4 Flash 0731Hosted API | 98.2%491/500 · 96.6%–99.1% | 567ms | 5948ms | $0.00802 | 0 |
| Llama 4 MaverickHosted API | 98.8%494/500 · 97.4%–99.4% | 575ms | 932ms | $0.02669 | 0 |
| GPT-4.1 NanoHosted API | 98.8%494/500 · 97.4%–99.4% | 605ms | 1011ms | $0.01404 | 0 |
| Mistral Large 3 2512Hosted API | 99.4%497/500 · 98.3%–99.8% | 628ms | 1161ms | $0.06944 | 1 |
| Qwen3 8BHosted API | 99.2%496/500 · 98.0%–99.7% | 645ms | 849ms | $0.01668 | 0 |
| Gemini 3.1 Flash LiteHosted API | 99.2%496/500 · 98.0%–99.7% | 656ms | 922ms | $0.03277 | 0 |
| GPT-4.1Hosted API | 99.0%495/500 · 97.7%–99.6% | 656ms | 1028ms | $0.28076 | 0 |
| GPT-4.1 MiniHosted API | 99.2%496/500 · 98.0%–99.7% | 667ms | 1065ms | $0.05615 | 1 |
| Claude Haiku 4.5Hosted API | 98.8%494/500 · 97.4%–99.4% | 778ms | 981ms | $0.16044 | 0 |
| GPT-5.6 LunaHosted API | 98.2%491/500 · 96.6%–99.1% | 1145ms | 3423ms | $0.03228 | 0 |
| GPT-6 AstraHosted API · low reasoning | 99.6%498/500 · 98.6%–99.9% | 1349ms | 2721ms | $1.58390 | 0 |
| Claude Sonnet 5Hosted API | 98.6%493/500 · 97.1%–99.3% | 1719ms | 2111ms | $0.38084 | 0 |
| Qwen3 30B A3B Instruct 2507Hosted API | 99.0%495/500 · 97.7%–99.6% | 1830ms | 3262ms | $0.00849 | 0 |
| Llama 3.2 1B InstructHosted API | 9.8%49/500 · 7.5%–12.7% | 2342ms | 9875ms | $0.00858 | 398 |
| Claude Fable 5Hosted API · low reasoning | 99.4%497/500 · 98.3%–99.8% | 3209ms | 4232ms | $1.93940 | 0 |
| DeepSeek V4 Pro (0813)Hosted API · low reasoning | 99.8%499/500 · 98.9%–100.0% | 3294ms | 12529ms | $0.44780 | 0 |
| GPT-5.6 SolHosted API | 99.0%495/500 · 97.7%–99.6% | 3401ms | 6904ms | $0.31276 | 0 |
Download CSV ↓ · JSON + source records ↗ · *Errors are failed API calls or unparseable outputs, counted as incorrect. Other wrong answers are included in accuracy.
The cost estimate depends on how much you use the machine. Adjust its hourly cost and utilization below to compare local inference with an API.
Estimate your costs
Cost per 1,000 decisions
Explore the cost at your utilization.
Adjust the controls to explore the assumptions.
Local cost = measured warm inference time × allocated hourly cost ÷ utilization. Excludes training, setup, operations, cold starts and error remediation. API charges exclude credit purchase fees and tax. Hardware rates are assumptions, not vendor quotes. This calculator compares standalone inference; the gate cards also include fallback API charges.
Scope
This test measures request routing. Invoice audits and agent-action checks need separate evaluations. Our ERP development probe did not reach its 95% accuracy target; the proposed audit benchmark has not run.
Methodology
We used 500 frozen, in-scope queries from CLINC by Larson et al. (2019), licensed CC-BY-3.0, at a pinned revision. Each query has its correct intent plus seven randomly selected distractors, shuffled. This is narrower than full 151-label classification and excludes out-of-scope queries.
SmallDecide was trained on CLINC training data. The test excludes upstream training text and examples from the released evaluation archive. Foundation-model training exposure is unknown. The later three-model run reused this test after we had examined the original results, so it is exploratory.
API settings. The original 30-model run used a 128-token output cap, reasoning disabled where supported, and up to 24 requests in flight (four per model). Fable 5, Astra, and DeepSeek V4 Pro used low reasoning effort, a 4,096-token combined reasoning/output cap, and four requests in flight. Each model saw the same prompt and candidate answers. Labels were withheld; failed or unparseable responses counted as incorrect.
Timing. SmallDecide v0.3.0 ran sequentially on an Apple M4 Max using MPS. Timings include tokenization and synchronized inference, but exclude the 8.43-second model load. All other models were tested through hosted APIs; their serving hardware was not reported. API timings include the network and full response. Brief ERP probes also ran on the workstation during part of the API test. The chart reports these observed timings, rather than an isolated hardware comparison.
Cost. API costs are recorded OpenRouter charges, including reasoning tokens and provider discounts. The local estimate uses measured inference time at $0.50 per machine-hour and full utilization. Training, setup, operations, and error remediation are excluded. The displayed comparison uses the 30 APIs with complete billing; all source runs remain available below.
Replay. We reused the maximum-candidate-probability threshold chosen on 200 validation cases. Escalated requests add local time and API time. This estimates the gate’s cost and latency; it does not measure a deployed service or queueing. Accuracy differences and timings are single-run observations, not evidence of equal quality or a universal ranking.
Data and code
Inputs, predictions, charge records, protocols, and reproduction scripts for both API runs.
Comparison CSV · Comparison JSON · Gate replay · API protocol · Earlier Haiku experiment